
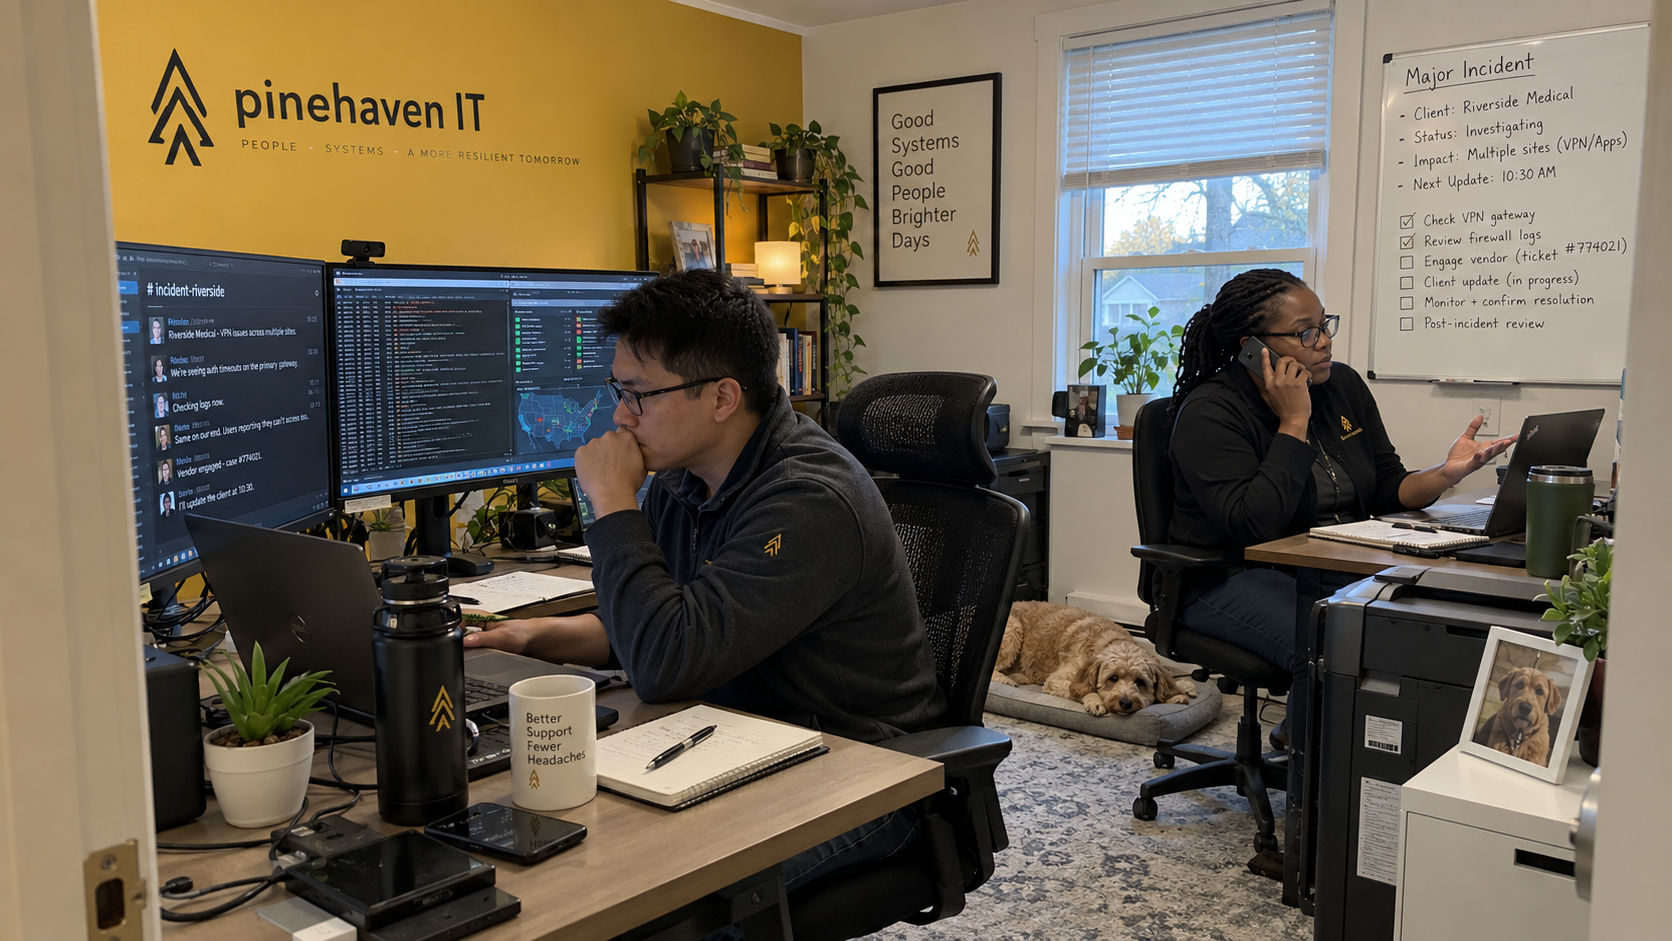
A major incident process for a small MSP needs named people who can direct recovery while someone protects the remaining support queue. Assign those responsibilities before an outage, agree how client updates will work, and make the after-hours handoff explicit. The process must fit the roster you have.
I'd keep a short operating sheet with the triggers and current contact details, backed by the technical recovery procedures your team already uses. During an incident, the lead should be directing work rather than discovering who can authorize it. Give each assignment a backup as well as an owner.
Use the Actual Team as the Starting Point
The MSP model's US example has 12.50 full-time equivalents across the business, including part-time roles. Its support desk has 4 technicians. That is an example staffing plan, not a claim that every MSP of roughly this size has the same structure.
The desk assumes a well-run rate of 0.5 tickets per seat per month; a typical MSP runs 1.0 to 1.4. In this model, a team lead dispatches from the pool rather than relying on a dedicated dispatcher. Your incident assignments need to reflect your own workload and who can be released from ordinary support.
Don't assign every available technician to the incident by default. Choose the skills the recovery needs, then name who keeps watching other clients. If you cannot cover both, make that conflict an explicit decision for the owner.
Give the Lead Clear Activation Triggers
A major incident is an event you choose to manage through coordinated recovery rather than normal ticket handling alone. I would define activation around business impact and the need to coordinate people. A stalled routine ticket needs help, but it does not automatically need the same process as a client-wide outage.
- Consider activation when a client or site cannot carry out essential work and the recovery requires coordinated action.
- Consider activation when related failures affect multiple clients and need investigation across shared systems or suppliers.
- Escalate suspected security incidents and material data-loss concerns to the appropriate response lead under the procedures you have agreed.
- Let the designated lead activate the process when the normal queue cannot safely coordinate the response. Record the reason and reassess it as facts improve.
These are recommendations to adapt to your client agreements and services. Put the activation authority on the operating sheet so the on-call engineer knows when they can call for help. An unnecessary escalation still uses people, so review those decisions rather than pretending they cost nothing.
Separate the Responsibilities Before Combining Jobs
My preference is to name the responsibilities separately even when the same person initially holds several. That makes it possible to hand one over without handing over the entire incident. The lead should check whether combined duties remain manageable as the work grows.
| Responsibility | Recommended Assignment | What They Own |
|---|---|---|
| Incident lead | The working lead, or the on-call engineer until a handoff | Coordinate the response, set priorities, maintain the incident record, and confirm who owns each action. |
| Technical recovery | The technicians with the required skills | Carry out assigned work, report findings, and flag dependencies or risks before changing the plan. |
| Client communication | A named account contact or another designated colleague | Send agreed updates and bring client decisions back to the lead. |
| Business decisions | The MSP owner and the client person authorized for the decision | Resolve spending, service tradeoffs, and other decisions beyond the technical team's authority. |
Assign technical work to a resource capable of doing it, consistent with the model's position on routing work. Pulling the owner into every diagnostic task is not a substitute for clear decision authority. Equally, an account contact does not acquire authority to approve client spending simply by sending the updates.
Keep a Record That Supports the Next Decision
Open an incident record that the response team can reach. Record the affected service and the observed business impact, distinguishing confirmed facts from the working explanation. Link related tickets so technicians can see the shared response without losing each client's context.
Give each recovery action an owner and record the result. If a handoff is needed, the receiving lead should confirm the current state and the next pending decision. A title on a contact list is not a handoff.
Keep the normal queue visible through a named colleague. New reports may change the incident's scope, while unrelated work still needs triage. The lead needs a route for both kinds of information without asking everyone to join every technical conversation.
Promise the Next Update, Then Send It
Agree the next update time at activation, based on the incident and the client's requirements. The communication owner sends the update even when the diagnosis has not changed. State what is known and what the team is checking, rather than supplying a confident explanation to fill the silence.
- The opening update identifies the affected service, the known impact, the response contact, and when the next update will arrive.
- Progress updates explain what has changed, any action required from the client, and the next update time.
- The recovery update states what has been verified as working, what remains unresolved, and who owns the remaining work.
Choose the communication channel before relying on the affected service to deliver messages. Keep alternate client contact details accessible under your normal access controls. If the client's usual email is unavailable, discovering another contact route becomes part of the delay.
Plan After Hours Without Guessing Incident Frequency
The model assumes 5% of all tickets arrive outside business hours and uses an on-call engineer as the default coverage. That ticket share does not tell you how major incidents are distributed across the day. Plan the after-hours incident response from the service you have agreed to provide.
Name who the on-call engineer can contact for technical help and business decisions. Check that those people have accepted the escalation arrangement. If the engineer transfers the lead role, make the transfer explicit rather than assuming the arriving colleague has taken over.
Close Recovery and Assign the Follow-Up
Confirm recovery against the affected service's expected operation, with client confirmation where appropriate. Keep unresolved risks visible after the main incident closes. Closing the coordination record should not erase the follow-up work.
Review the event once the people and records needed are available. Reconstruct what happened and how it was detected, then examine what helped or delayed recovery. Convert the useful changes into assigned work with completion dates and check that they reach the queue.
For the first rehearsal, choose a service your team actually supports and walk through who activates the process. Follow the contact chain through a plausible after-hours absence, then check who covers ordinary support. Fix the missing assignment before treating the sheet as ready.
mspoutpost.com/articles/a-major-incident-process-for-a-12-person-msp
Written by Megan Friesen
MSP Outpost publishes information, not legal, financial, insurance, tax or compliance advice, and reading it creates no professional relationship. For decisions about your business, talk to a qualified professional.