
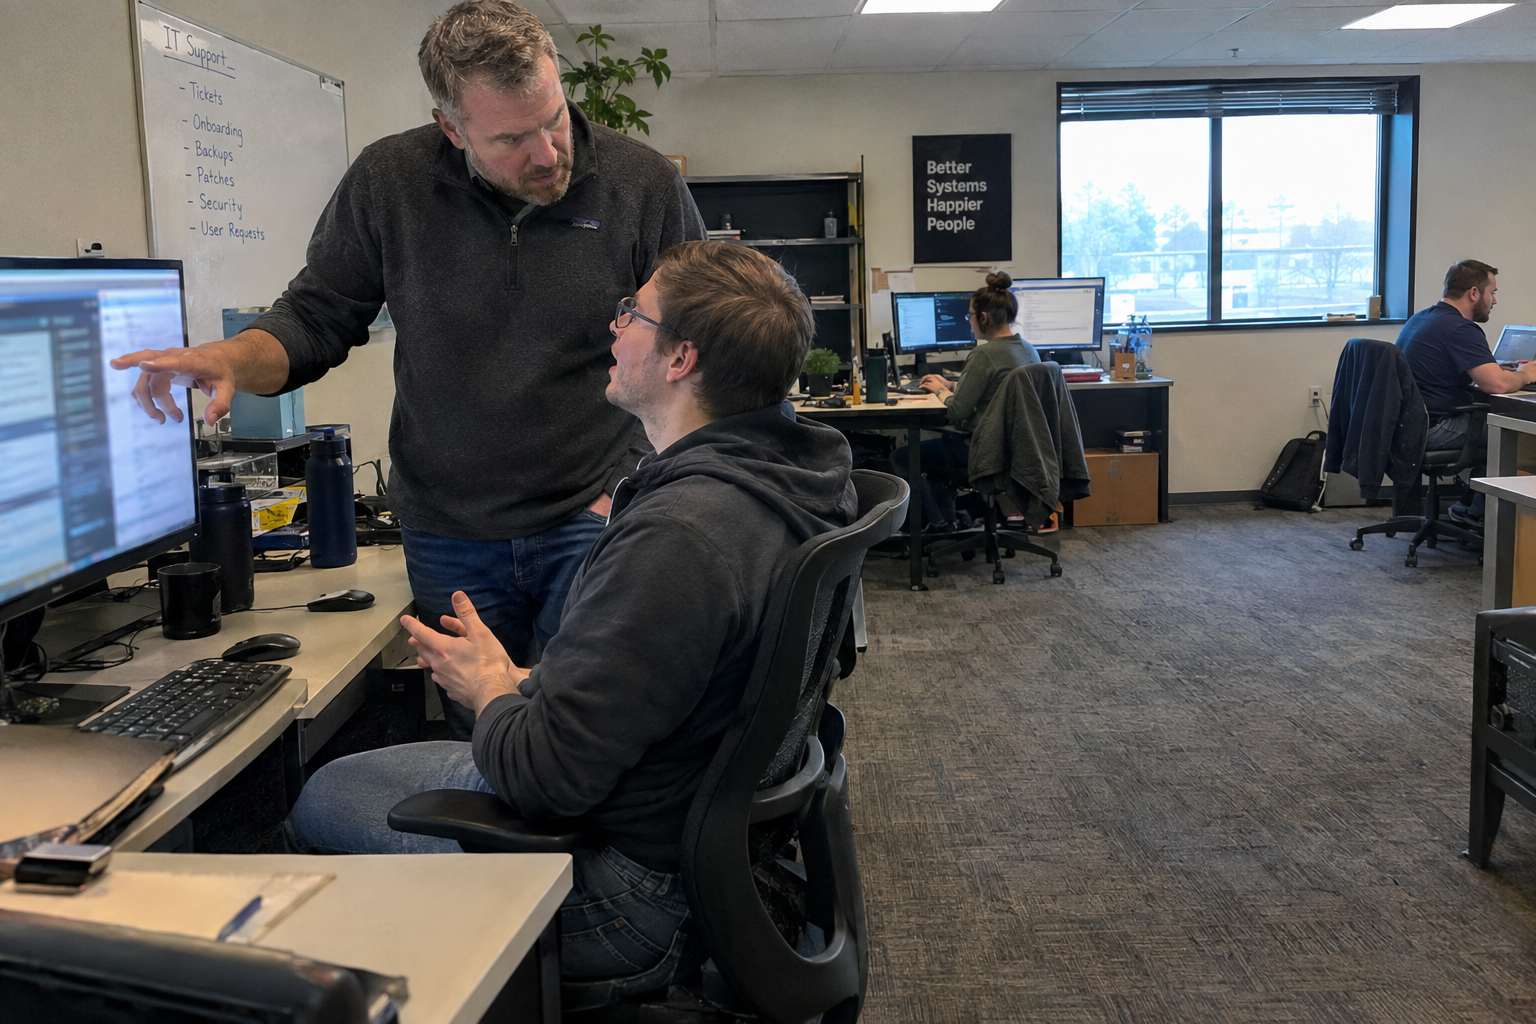
Picture a reset-password ticket. Should take ten minutes. It's been open for half an hour, the SLA timer is still running, and your Tier 1 tech is quiet on the board. You have two moves: let it ride until the client calls, or check in now and teach something.
The answer is a 30-minute stuck-ticket check-in. When a Tier 1 ticket has no status change for 30 minutes, the tech flags it, a senior checks in, and after escalation there's a coaching session. It's a coaching trigger, not a performance stick. Thirty minutes is a default for mid-severity tickets only, and you'll adjust it for what your desk actually carries.
What the 30-Minute Rule Is (and Isn't)
The rule is simple: a T1 ticket with no status change for 30 minutes gets flagged. A senior or lead checks in with the tech, asks what's blocking, and takes it over if it needs to move. After the escalation, the senior walks the tech through what happened and where the bottleneck sat.
It is not a performance metric. It is not a shaming tool. If your team reads it as a trap, they'll hide stuck work instead of flagging it, and you'll be back where you started with a quieter board.
Say the tech's ticket gets flagged and they say "waiting on client." The senior looks and sees it's been waiting for an hour. That's the coaching moment: when do you ping the client versus escalate? The check-in makes that conversation happen on purpose, not after the SLA breaks.
When to Shorten, Lengthen, or Skip the Timer
Thirty minutes is a default for mid-severity tickets. It is not universal. High-severity tickets, a server down or a network outage, need a 10 to 15 minute timer and direct escalation, not a check-in. Low-severity tickets, a printer jam or a single-user email quirk, can wait 60 minutes without anyone losing sleep.
How do you decide severity? Some owners say the deciding factor is how many systems are affected and whether the client can do any work at all. A network outage escalates immediately, no timer attached.
Your queue volume matters too. On a day when tickets are stacking and you're short-staffed, a check-in every 30 minutes becomes a distraction. Flex the interval or batch the reviews. The rule is a tool for your desk, not a mandate you serve.
Roll Out the Rule Without Making Your Team Feel Watched
How you introduce this decides whether it works. If you tie it to individual performance, it will read as a trap, and your techs will game the status field instead of asking for help. Frame it as what it is: we all get stuck, this helps us unstick each other.
Here's a script for the team meeting: "When you're stuck for 30 minutes, flag it. That's a signal for us to help, not a ding." Say it plainly and mean it. The first time a tech flags a ticket and gets coached instead of scolded, the rule becomes real.
One caution: some owners have used stale-ticket metrics and spot-checking to catch techs who fake schedule entries to dodge SLA. That's a different tool for a different problem. Don't bolt it onto this. If your team thinks the check-in is surveillance, you've lost the coaching value before you start.
What Happens After the Escalation: Coaching, Not Blame
After the senior takes over the ticket, the real work begins. Sit with the tech for ten to thirty minutes and review what happened. Diagnose the bottleneck: was it tooling, knowledge, or waiting on the client? Then teach the fix and have the tech document it.
Say the tech didn't know the RMM script for password resets. The senior shows it, the tech runs it, and the tech writes a note in the knowledge base. Next time, that ticket closes in ten minutes, and you've bought the coaching time back on the next dozen tickets.
This only works if the senior has time. On a busy day when the senior is buried in their own escalations, coaching gets skipped, and the rule quietly dies. If that's your reality, schedule the coaching session for end of day or the next morning, but schedule it. Unfinished coaching is the same as no coaching.
When This Rule Won't Save You: Coverage, Culture, and Tooling
The 30-minute rule fails under four conditions, and you should know them before you start.
- Your PSA can't surface tickets with no status change for 30 minutes, and you don't build a manual review ritual. Without a way to see stale tickets, the rule becomes a memory exercise and dies by Wednesday.
- Senior staff are too busy to coach. If coaching never happens, the check-in is just a faster escalation, and your juniors learn to hand off instead of learning the fix.
- Coverage breaks. On a two-person desk where both techs are on calls, nobody owns the check-in. Some owners running small shops with part-time contractors say coverage is the first thing to plan for, before the timer.
- Culture is the fourth condition. If your team already hides stuck work, the rollout script has to name that fear directly. Say it in the meeting: "This is not a trap. We are not tracking who gets stuck. We are tracking where the desk needs help." Repeat it until it's true in practice.
Start Monday
Pick one severity tier, mid-severity, and set the timer for a week. Tell the team what's happening and why. When the first ticket flags, do the check-in, do the coaching, and see what you learn. Adjust the interval if the queue can't sustain it. Then decide if the rule earns a permanent spot.
Thirty minutes isn't sacred. The coaching is.
mspoutpost.com/articles/your-tier-1-tech-has-been-stuck-on-that-ticket-for-30-minutes
Written by Megan Friesen
MSP Outpost publishes information, not legal, financial, insurance, tax or compliance advice, and reading it creates no professional relationship. For decisions about your business, talk to a qualified professional.