An auditor asks a simple question: "Show me that a restore actually works." You open the backup console and point at green checkmarks. That isn't proof. It's hope with a timestamp.
The answer is a proof-of-restore program: a per-client inventory of what's backed up, a quarterly restore test that verifies data is accessible, and recovery steps written before anyone is panicking. None of it is glamorous. All of it turns "we back you up" into "we proved we can get you back."
What If You Had to Restore Right Now?
Picture the call. A client's server died at 11pm and the owner wants to know when their data is coming back. You have no tested answer. You have a backup log that says the job completed, which tells you nothing about whether the restore will finish in an hour or a day.
One MSP found this out the hard way. They tested an annual restore of a 1TB compressed image and watched the transfer take four to six hours even inside their own ecosystem. That number is the kind of thing you want before the crisis, not during it.
So what do you test, and how often? That's the next question, and it starts with knowing what you're protecting.
Audit What Is Actually Backed Up, Client by Client
You can't test a restore if you don't have a single record of what's backed up. If the inventory lives in one person's head, assume that person will be on holiday the week it matters.
Build a client-by-client inventory: source systems, data stores, backup destination, retention period, and the person to contact for a restore. Say a client's server room floods and you have to rebuild two servers from the cloud overnight. That recovery depends on knowing exactly what sat on each source server.
Your backup console may auto-generate some of this. Verify it manually anyway. The inventory is only as good as the last time you updated it, and client environments change more often than you'd like.
Keep the inventory in a shared template, not in a ticket or a chat thread. Update it every time a workload or a backup job changes. Stale documentation is worse than none, because it gives you false confidence.
Once you know what's backed up, the real question appears: how do you prove a restore actually works?
Run a Quarterly Restore Test That Proves Accessibility
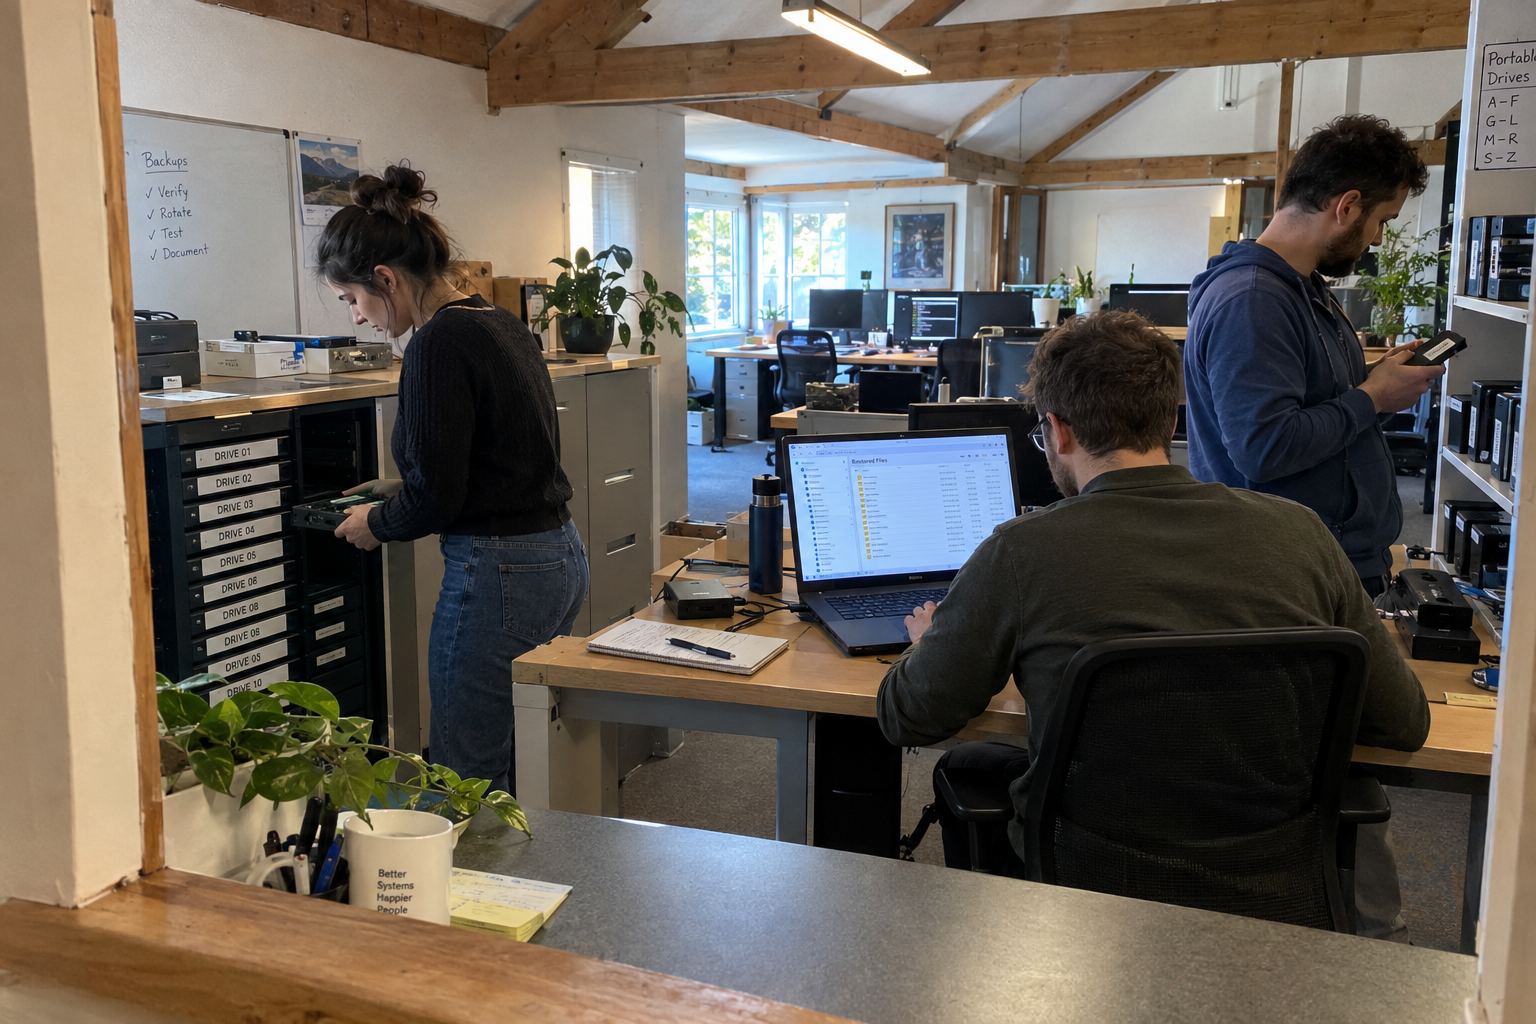
Quarterly is the cadence I'd start with. One test per client, alternating between file restore, server restore, and full failover for clients that pay for disaster recovery. Record the result in a standard report: what you tested, how long it took, what failed, what you fixed.
The critical part is what "passing" means. A VM that boots is not a working service. One MSP ran a real full failover of their DRaaS platform and discovered that booting the VMs alone proved nothing. They had to test DNS run-books, IP changes, and VPN updates before anything was reachable.
Testing depth is a trade-off. A file restore is quick and catches the basics. A full failover takes longer and catches what actually breaks. My view: alternate between them, and be honest with clients about what each test proves.
A passing file restore does not prove a server restore works. A booting VM does not prove a service is reachable. Test what you promise, and verify accessibility, not just existence.
Quarterly testing of every client may exceed what a small team can absorb. Stagger the tests across the quarter, or prioritize high-risk clients and accept annual full tests for the rest. That shifts risk, so say so out loud. It's better than promising quarterly and delivering nothing.
Now that you have a test that proves something, what has to be written down so the next person can run it without you?
Write Recovery Steps Before You Need Them
A run-book for each client covers two things: restoring the data, and making it reachable. The restore steps come from your backup tool. The accessibility steps come from what your quarterly tests revealed: DNS changes, IP updates, VPN configuration, authentication, web, database.
Your quarterly tests will show you where this bites: a VM that boots, but that nothing can reach until DNS and the supporting services are reconfigured. That's the document you want at 2am, written by someone who tested it, not improvised by whoever answers the phone.
Include who to contact: the client's decision-maker, the person with access to the firewall, the vendor who owns the line. Names go stale, so review the run-book when the inventory changes and at least annually.
This all sounds reasonable until the week you're busy. Where does this routine actually fall apart?
Know When Your Test Program Will Not Save You
The program fails when client environments change between tests and nobody updates the inventory. It fails when testing gets skipped because a ticket backlog ate the quarter. It fails when you only do file restores for a VM environment and call it done.
Cloud restores can take hours, and that's worth planning around. One MSP restored from S3 to a temporary instance and found it worked, just slowly. Those tested numbers set realistic expectations with clients about RTO. If your client believes a large database comes back in ten minutes, you're setting up a very bad Tuesday.
My read is that the failure mode isn't the tools. It's the discipline. A quarterly test that gets skipped once becomes a semi-annual test that becomes a hope. Guard the schedule like you guard the backups themselves.
So where do you start on Monday, when the quarter is already half gone?
Monday's First Action: Pick One Client and Verify a File Restore
Choose one client with a simple backup. Pick a file, restore it to a test location, and confirm you can open it. Document the result in a shared template: what you restored, how long it took, what you had to fix.
That single verification will tell you more than a year of green checkmarks. It will reveal whether your backup tool actually restores data, whether your documentation matches reality, and what your real restore time looks like.
Then pick the next client next quarter. The program builds one verified restore at a time, and each one is evidence you can put in front of an auditor, or a client, or yourself at 2am.
mspoutpost.com/articles/prove-your-backups-work-before-the-day-a-client-needs-them
Written by Dana Kowalski
MSP Outpost publishes information, not legal, financial, insurance, tax or compliance advice, and reading it creates no professional relationship. For decisions about your business, talk to a qualified professional.